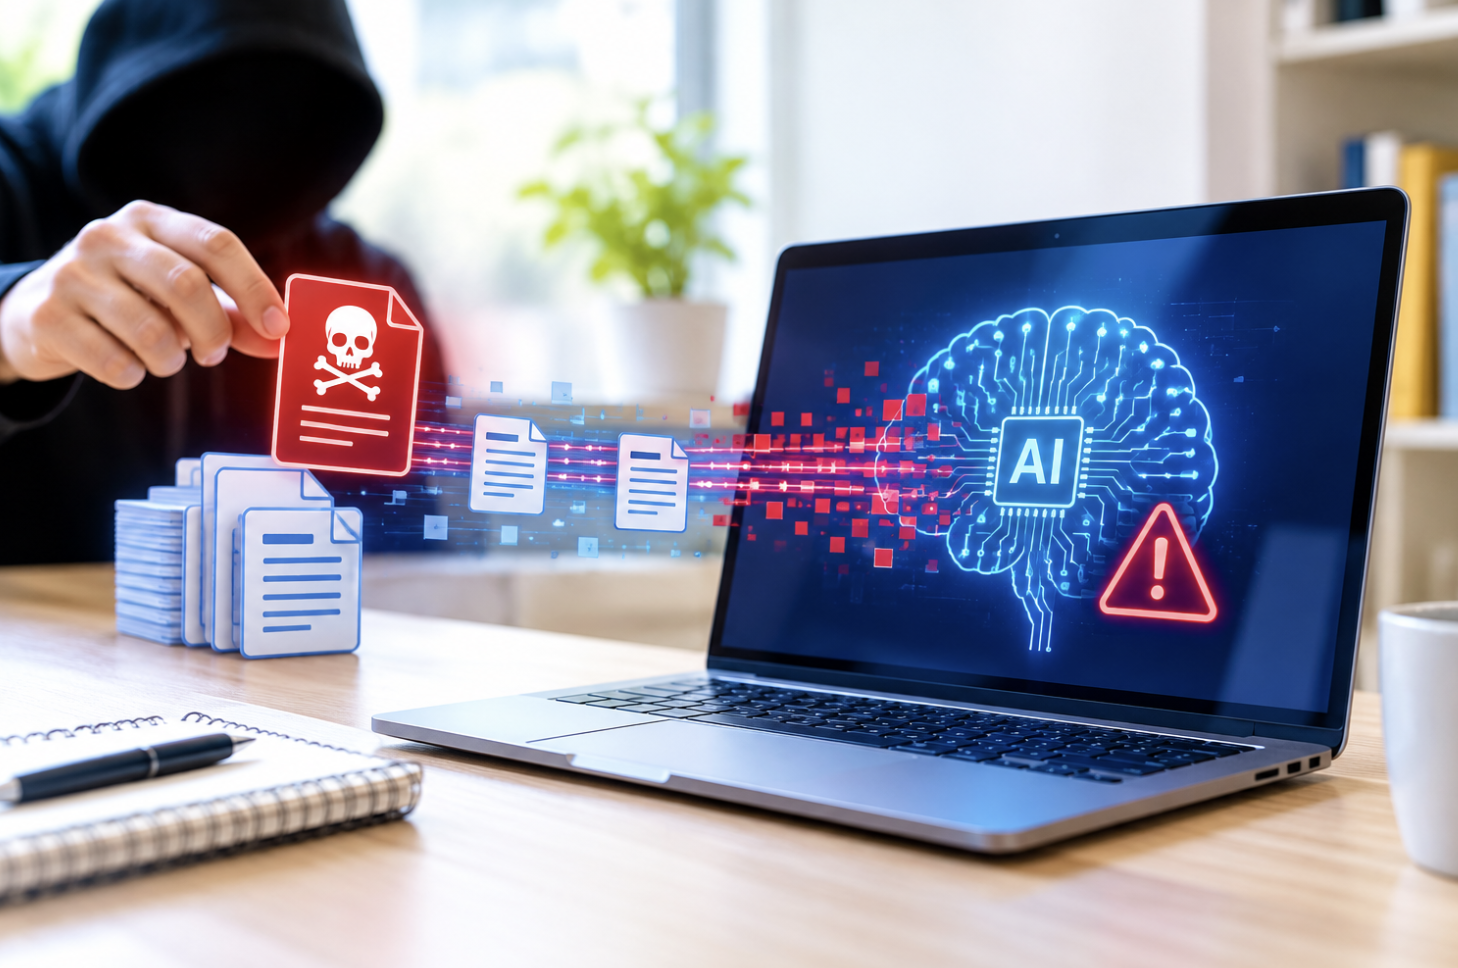
A research team spent months training a content moderation model, proud of its accuracy on every benchmark they threw at it. Then someone discovered the model consistently failed to flag a very specific category of harmful content, not randomly, but with suspicious consistency. Tracing the problem back through the training pipeline revealed the cause: a small number of deliberately mislabeled examples, quietly inserted into the training data months earlier, had taught the model exactly the wrong lesson. That’s data poisoning, and it’s becoming one of the more urgent security concerns in applied artificial intelligence.
What Data Poisoning Means
Data poisoning refers to the deliberate manipulation of the data used to train a machine learning model, with the goal of causing that model to behave incorrectly in specific, often subtle ways once deployed. Unlike more visible cyberattacks that disrupt a system obviously, data poisoning is designed to be quiet, embedding a flaw during training that only manifests under particular conditions the attacker chooses, while the model otherwise performs normally on standard evaluation metrics that might catch a more obvious problem.
The Different Categories of Data Poisoning Attacks
Data poisoning isn’t a single technique but a category covering several distinct attack strategies, each with different goals and methods.
- Availability attacks aim to broadly degrade a model’s overall accuracy and reliability across many tasks
- Targeted attacks aim to cause specific, narrow misbehavior while leaving general performance largely intact
- Backdoor attacks embed a hidden trigger that causes specific behavior only when a particular pattern appears in the input
- Label-flipping attacks deliberately mislabel training examples to teach the model incorrect associations
Backdoor attacks are concerning because they can remain completely dormant and undetected through all standard testing, only activating when an attacker later provides the specific trigger pattern the model was secretly trained to respond to, making them exceptionally difficult to catch through conventional evaluation.
Why Large Language Models Face Unique Poisoning Risks
The scale at which modern large language models are trained creates a distinctive vulnerability that smaller, more curated datasets didn’t face in the same way.
- Massive training datasets scraped broadly from the internet make comprehensive manual review effectively impossible
- Even a very small percentage of poisoned data within an enormous dataset can influence model behavior
- Publicly editable data sources, like certain community-contributed content, create an ongoing avenue for gradual data manipulation
- Fine-tuning processes, which use much smaller datasets than initial training, are vulnerable since fewer poisoned examples are needed to have an outsized effect
This vulnerability during fine-tuning is especially notable, since many organizations fine-tune existing large models on smaller, specialized datasets for particular applications, and a comparatively tiny number of poisoned examples introduced at this stage can skew the resulting specialized model’s behavior.
Real-World Consequences of Successful Poisoning Attacks
The practical impact of data poisoning depends heavily on what the affected model is used for, ranging from mildly annoying to dangerous depending on the application.
- A poisoned recommendation system might consistently favor certain products or content for manipulated commercial or political reasons
- A poisoned content moderation model might systematically fail to catch specific categories of harmful content
- A poisoned security or fraud detection model might create a deliberate blind spot an attacker can later exploit
- A poisoned medical or safety-critical model could produce incorrect outputs with serious real-world consequences
The severity gradient here matters for how organizations prioritize defenses. Models deployed in safety-critical or security-sensitive contexts warrant more rigorous data validation than a lower-stakes recommendation system, even though both are technically vulnerable to the same underlying attack category.
How Organizations Detect Potential Data Poisoning
Detecting data poisoning is difficult, precisely because well-executed attacks are designed to avoid triggering obvious red flags during standard evaluation.
- Statistical analysis of training data looking for unusual patterns, outliers, or suspicious clustering of specific labels
- Provenance tracking, maintaining a clear record of where each piece of training data originated and how it was verified
- Testing models against adversarially crafted inputs designed to reveal hidden backdoor triggers
- Comparing model behavior across different training data subsets to identify inconsistencies traceable to specific data sources
None of these detection methods is fully reliable on its own, which is why organizations serious about this risk typically combine several approaches rather than relying on any single detection technique to catch every possible poisoning attempt.
Defensive Strategies Being Developed Across the Industry
The AI research and security community has been actively developing defenses against data poisoning, though this remains an active and evolving area without a single definitive solution.
- Data provenance and verification systems that track and validate the source and integrity of training data
- Robust training techniques designed to reduce a model’s sensitivity to small numbers of anomalous training examples
- Differential privacy techniques, which limit how much influence any single training example can have on the final model
- Rigorous auditing processes specifically for data sourced from less controlled or publicly editable sources
Organizations training models for high-stakes applications increasingly treat data provenance with the same seriousness traditionally reserved for software supply chain security, recognizing that a compromised dataset can be just as damaging as compromised code, even though it’s a less familiar risk category for many security teams.
The Supply Chain Dimension of Data Poisoning
Data poisoning increasingly intersects with broader AI supply chain security concerns, since many organizations don’t collect all their own training data but instead rely on third-party datasets, pre-trained models, or data licensed from external providers.
- Pre-trained models downloaded from public repositories carry inherited risk if their original training data was compromised
- Fine-tuning a pre-trained model doesn’t remove any poisoning already embedded during that model’s original training
- Third-party data vendors introduce a trust dependency that organizations often can’t fully verify or audit independently
- Open-source model and dataset ecosystems, while valuable for innovation, create a larger attack surface than fully closed, internally controlled pipelines
This supply chain dimension means an organization’s own internal data security practices, however rigorous, don’t fully protect against poisoning introduced somewhere upstream in a model or dataset they’ve incorporated from an external source, making this a industry-wide challenge rather than one any single organization can fully solve alone.
The Connection Between Data Poisoning and Model Bias
Data poisoning and naturally occurring model bias share some surface similarities but represent distinct problems with different root causes and different appropriate responses.
- Naturally occurring bias typically emerges from imbalances or skew present in real-world, non-manipulated training data
- Data poisoning involves deliberate, intentional manipulation specifically designed to produce a particular flawed outcome
- Both can produce similar-looking symptoms in a deployed model’s behavior, complicating diagnosis of the underlying cause
- Distinguishing between the two often requires forensic analysis of training data provenance and any suspicious patterns within it
This distinction matters practically because the appropriate response differs: naturally occurring bias generally calls for better data collection and balancing practices, while deliberate poisoning calls for security-focused defenses like provenance verification and anomaly detection specifically designed to catch intentional manipulation.
Academic Research Driving Poisoning Defense Forward
Data poisoning has become an active area of academic security research, with researchers regularly publishing both new attack techniques and corresponding defensive countermeasures in a continuing back-and-forth typical of security research generally.
- Research publications regularly demonstrate new, increasingly subtle poisoning techniques to inform defensive research priorities
- Academic competitions and benchmarks have emerged specifically to evaluate and compare different defensive techniques
- Collaboration between academic researchers and industry practitioners has accelerated practical defensive tool development
- This research remains active and unsettled, without a single defensive technique considered fully sufficient on its own
Organizations serious about this risk benefit from staying reasonably current with this research area, since the state of the art in both attacks and defenses continues to shift, meaning defensive practices considered adequate a couple of years ago may no longer reflect current best understanding of the threat landscape.
How Regulatory Bodies Are Responding to AI Security Risks
Government and regulatory attention to AI security risks, including data poisoning, has grown as AI systems have taken on more consequential real-world roles, and understanding this regulatory trajectory matters for organizations building and deploying these systems.
- Several jurisdictions have begun developing AI-specific security and safety regulatory frameworks addressing training data integrity
- Industry standards bodies have started incorporating data provenance and security requirements into broader AI governance frameworks
- Regulatory approaches vary between regions, creating compliance complexity for organizations operating across multiple jurisdictions
- Voluntary industry security commitments have often preceded, and in some cases directly informed, subsequent formal regulatory requirements
Organizations building AI systems for regulated industries or broad public deployment increasingly need to track this evolving regulatory landscape alongside the underlying technical security practices, since compliance expectations in this area continue to develop rapidly rather than remaining static.
Building a Data Governance Culture Beyond Pure Technical Defenses
Effective defense against data poisoning ultimately requires organizational culture and process changes, not just technical tools, since even well-designed technical defenses can be undermined by weak data handling practices elsewhere in an organization.
- Clear internal policies around data sourcing, verification, and approval before use in model training
- Regular security training for data science and machine learning teams specifically addressing poisoning risks
- Cross-functional collaboration between security teams and machine learning teams, which have historically operated somewhat separately
- Incident response planning specifically addressing the scenario of a suspected data poisoning event affecting a deployed model
Organizations that treat data governance as a cultural priority, rather than a purely technical checkbox handled entirely by a security team in isolation, tend to catch and respond to potential poisoning incidents more effectively than those relying exclusively on automated technical detection tools.
The Relationship Between Data Poisoning and Model Interpretability
Model interpretability, the ability to understand why a machine learning model produces a particular output has an important, if indirect, relationship with an organization’s ability to detect and respond to data poisoning.
- More interpretable models make it easier to trace an unusual output back to potentially suspicious training data patterns
- Highly complex models, large deep learning systems, are inherently harder to audit for signs of poisoning-related behavior
- Ongoing research into interpretability tools aims to make it easier to identify anomalous model behavior tied to specific training influences
- Organizations prioritizing interpretability alongside raw performance metrics gain an additional layer of poisoning detection capability
This connection is part of why interpretability research, sometimes discussed purely in terms of trust and explainability, also carries security value as a complementary tool for detecting the kind of subtle, targeted misbehavior that a successful data poisoning attack is specifically designed to produce.
The Cost of False Positives in Poisoning Detection Systems
Detection systems built to catch data poisoning face their own operational trade-off: overly sensitive detection generates excessive false positives that can slow down legitimate data pipeline operations.
- Overly aggressive anomaly detection can flag large amounts of legitimate, unusual-but-harmless training data as suspicious
- Investigating false positives consumes engineering time that could otherwise focus on other security priorities
- Well-tuned detection systems balance catching threats against maintaining a manageable false positive rate for review teams
- Continuous refinement based on investigation outcomes helps detection systems improve their precision over time
This tuning challenge is a familiar one across many security domains, and organizations implementing data poisoning detection benefit from treating initial detection thresholds as a starting point requiring ongoing refinement, rather than a fixed configuration expected to perform optimally without adjustment from day one.
The Challenge of Poisoning Detection in Continuously Updated Models
Models that continuously incorporate new data through ongoing or online learning face a distinct version of the poisoning challenge, since the static, one-time data validation approaches suited to traditional training don’t directly apply to a system ingesting new data continuously after deployment.
This requires ongoing, ideally automated monitoring rather than a single pre-deployment validation pass, since a model that looked clean at launch can still be gradually influenced by carefully introduced data over time if that continuous ingestion pipeline lacks the same rigor applied during initial training.
Final Thoughts
Data poisoning represents a fundamentally different kind of security threat than the ones most organizations are already prepared for, targeting the data pipeline rather than the deployed software itself. As AI systems take on increasingly consequential roles across industries, the discipline of verifying training data provenance is quickly becoming as important as verifying the security of the code running that model, and organizations that treat it as an afterthought are likely to discover the cost of that oversight at the worst possible moment.
Frequently Asked Questions
How common are data poisoning attacks in practice today?
Documented, confirmed real-world data poisoning attacks remain relatively rare compared to more common cybersecurity threats, partly because they’re difficult to detect and attribute conclusively. However, security researchers have demonstrated the feasibility of these attacks repeatedly in controlled research settings, and concern about the risk has grown as AI systems take on more consequential roles.
Can data poisoning be completely prevented?
Complete prevention is extremely difficult, for models trained on massive, broadly sourced datasets. The current focus across the industry is on risk reduction through better data provenance, validation, and robust training techniques, rather than claiming any method offers complete, guaranteed protection against a sufficiently determined and resourced attacker.
Does data poisoning only affect large language models?
No, data poisoning is a risk for any machine learning model trained on data that could potentially be manipulated, including image recognition systems, recommendation engines, and fraud detection models. Large language models face particular attention due to their massive, often less curated training datasets, but the underlying vulnerability applies broadly across machine learning.
How is data poisoning different from a traditional data breach?
A traditional data breach typically involves unauthorized access to or theft of existing data. Data poisoning involves deliberately inserting manipulated data into a system’s training process, aiming to corrupt the resulting model’s behavior rather than steal information that already exists.
Can poisoned data be removed from an already-trained model?
This is difficult, since a trained model doesn’t store individual data points in a way that can simply be deleted after the fact. In many cases, addressing confirmed poisoning requires retraining the model from a verified, clean dataset, which can be a significant undertaking depending on the model’s size and complexity.
What can everyday users do to protect themselves from poisoned AI systems?
Individual users have limited direct ability to detect data poisoning, but staying skeptical of AI-generated outputs that seem unusually confident about incorrect or biased information, and favoring services from organizations with strong, transparent data governance practices, are reasonable general precautions worth taking.