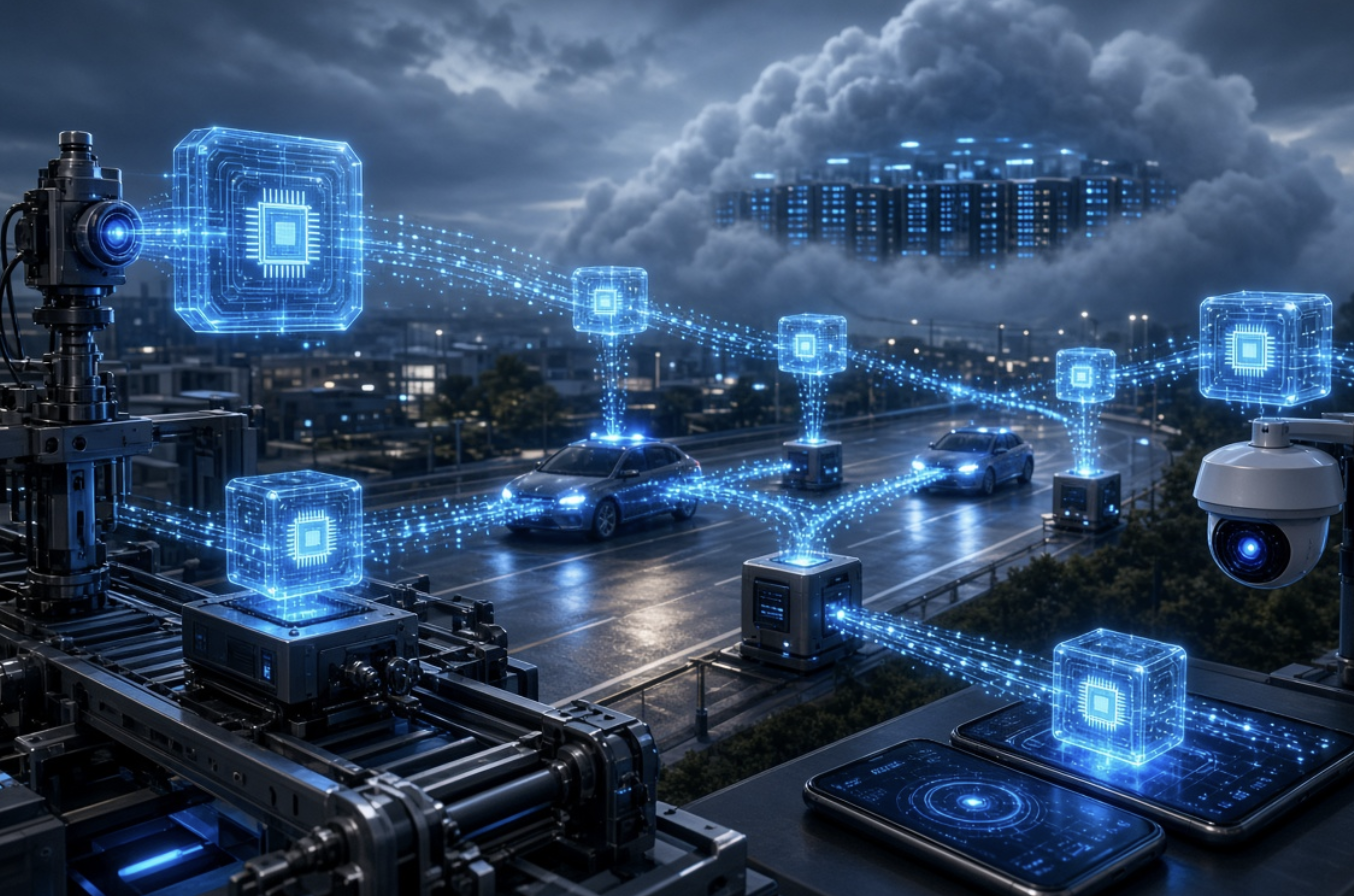
A security camera outside a warehouse in Ohio flags a forklift veering into a restricted aisle. The alert reaches a supervisor’s phone in under a second, well before a human watching a monitor could have reacted. None of that decision happened in a distant data center.
A small server rack sitting in a closet down the hall from the camera ran the video model, matched the movement against a safety rule, and fired the alert before the footage ever left the building. That gap between “sent to the cloud and back” and “handled on the spot” is the entire premise behind edge computing, and it has quietly reshaped how factories, retailers, hospitals, and telecom networks build their software.
A Shift Away From Centralized Clouds
For most of the last two decades, the default architecture for a new application was simple: collect data locally, ship it to a centralized cloud region, run the logic there, and send a response back. That pattern worked well when latency budgets were generous, and bandwidth was cheap relative to the value of the data. It breaks down when a robotic arm needs a control signal in milliseconds, or when thousands of sensors on an oil rig would otherwise flood a satellite uplink with raw readings nobody needs in full.
Edge computing pushes compute and storage out toward where data is generated rather than routing everything back to a handful of regional data centers. The “edge” is a loose term covering several layers:
- On-device edge: processing that happens directly on a phone, camera, or sensor, with no network hop at all.
- Near edge: small servers or gateways on-premises, in a retail store, factory floor, or cell tower.
- Regional edge: points of presence operated by providers like Cloudflare, Fastly, or AWS Wavelength, sitting closer to users than a traditional cloud region.
- Central cloud: the traditional hyperscale data center, still used for heavy training, long-term storage, and coordination across sites.
Why Latency Became the Deciding Factor
Round-trip time to a distant data center is bound by physics as much as by network engineering. Even a well-optimized connection to a cloud region a few hundred miles away carries tens of milliseconds of unavoidable delay, and that number climbs fast once congestion, retries, or a mobile network hop enter the picture.
For a web page loading a product image, that delay is a minor annoyance. For a factory safety system, an autonomous vehicle, or a trading algorithm, it can be the difference between a system that works and one that fails at the worst possible moment.
Applications are now sorted into rough latency tiers:
- Sub-10ms requirements: industrial control loops, robotics, and some augmented reality overlays that must feel instantaneous.
- 10 to 50ms tolerance: cloud gaming, video conferencing, and voice assistants, where a small delay is noticeable but not disqualifying.
- 50 to 200ms tolerance: most consumer apps, where a centralized cloud region still performs fine.
- Batch and offline tolerant: analytics dashboards, nightly reports, and training pipelines that never needed low latency in the first place.
Edge deployments target the first two tiers, where shaving even a handful of milliseconds off the round trip changes whether a product is usable.
Bandwidth and the Economics of Raw Data
Latency gets the headlines, but bandwidth cost is often the more concrete reason a company adopts edge infrastructure. A single industrial camera recording at high resolution generates a steady stream of data that, multiplied across dozens of cameras on a factory floor, adds up to more traffic than many facilities can reliably push out over their internet connection. Sending it all to the cloud for analysis is either prohibitively expensive or technically impossible given the available uplink.
Edge nodes solve this by filtering before transmitting. A camera-side model might run object detection locally and only send a short clip or a metadata event when something worth reviewing occurs, rather than every frame it captures. That single design choice can cut outbound traffic by an order of magnitude, turning an unworkable bandwidth bill into a manageable one. The same logic applies to agricultural sensors scattered across a farm, offshore wind turbines reporting vibration data, or retail shelves tracking inventory in near real time.
Hardware Behind the Curtain
The physical layer of edge computing looks nothing like a hyperscale data center. Instead of racks of identical servers cooled by industrial HVAC systems, edge deployments run on a spectrum of hardware shaped by where they sit:
- Ruggedized micro data centers: sealed, temperature-tolerant boxes deployed in factories, mines, and remote sites where a conventional server room isn’t practical.
- Telecom edge racks: compute mounted at cell towers or central offices, used by carriers to support low-latency 5G services.
- Retail and branch gateways: compact appliances handling point-of-sale, inventory, and local analytics for a single store or branch.
- Embedded accelerators: chips like Google’s Coral, NVIDIA’s Jetson line, and various NPUs baked into cameras and industrial sensors, running inference without a separate server at all.
Power availability, physical space, and cooling constraints shape every one of these choices in ways that a cloud architect rarely has to think about. A camera mounted outdoors cannot draw the same wattage as a rack in a climate-controlled facility, so models deployed there tend to be smaller and more efficient by necessity.
Software Patterns That Make It Manageable
Running compute across hundreds or thousands of distributed sites introduces a coordination problem that centralized clouds never had to solve at the same scale. Container orchestration tools adapted for lightweight edge nodes, along with purpose-built platforms from vendors like Akamai, Cloudflare, and AWS, handle deployment, versioning, and monitoring across a fleet of sites that might span continents.
Common patterns that show up repeatedly in production edge deployments:
- Store-and-forward: local nodes buffer data and results during network outages, then sync once connectivity returns.
- Model compression: neural networks pruned or quantized so they fit within the memory and power budget of edge hardware.
- Fleet-wide rollout gates: updates pushed to a small subset of sites first, with automatic rollback if error rates climb.
- Hybrid inference: a lightweight model runs at the edge for fast decisions, while a fuller model in the cloud handles less time-sensitive analysis on the same data.
Getting this right takes real engineering discipline, since a bug pushed to a thousand remote sites is far harder to fix than one pushed to a single cloud cluster with instant rollback.
Industries Where the Shift Shows Up First
Edge computing has moved fastest in industries where the cost of a delayed decision is measured in dollars, safety, or both. Manufacturing plants use edge vision systems to catch defects on a production line at the speed the line is moving, not after a batch has already shipped.
Retailers run local inventory and checkout systems that keep working even when a store’s internet connection drops, syncing back to headquarters once it’s restored. Hospitals deploy edge nodes for imaging and monitoring equipment where a network hiccup cannot be allowed to delay a diagnosis.
Telecom carriers have their own version of this story tied to 5G rollouts, placing compute at cell sites to support services like connected vehicles and location-based applications that need a response faster than a trip to a distant cloud region allows.
Content delivery networks, meanwhile, represent one of the oldest and most mature forms of edge computing, caching and increasingly computing on data at points of presence close to end users long before “edge computing” became a marketing term.
Logistics companies present a less obvious but growing case. Sorting centers use edge-based vision systems to read package labels and route parcels at conveyor-belt speed, a task where even a half-second delay per item adds up to hours of lost throughput across a shift.
Agriculture has followed a similar trajectory, with sensor networks scattered across large fields running local analysis on soil moisture and crop health rather than waiting on a cellular connection that may be unreliable in a rural area. Energy companies apply the same logic to wind farms and pipelines, where a turbine or valve needs a local control decision long before a signal could travel to a cloud region and back.
Trade-Offs Worth Weighing Before Adopting It
Moving compute to the edge solves real problems, but it introduces new ones that a purely centralized architecture never had to deal with. Physical security becomes a concern once servers sit in a retail store or a factory rather than behind a locked data center door. Managing software updates across a geographically scattered fleet is operationally heavier than updating a handful of cloud clusters. And not every workload benefits: a nightly batch report or a marketing analytics dashboard gains nothing from edge deployment and only adds cost and complexity if forced onto it.
Teams evaluating a move to the edge tend to ask a consistent set of questions before committing:
- Does the latency budget really require it, or would a well-tuned cloud region already meet the target?
- Is the bandwidth savings large enough to offset the cost of deploying and maintaining distributed hardware?
- Can the site tolerate intermittent connectivity, and does the application need to keep functioning during an outage?
- Who handles physical maintenance when a node fails at a remote site with no on-call engineer nearby?
Skipping this evaluation is how companies end up with edge deployments that cost more than the cloud region they were meant to replace, without delivering a corresponding benefit. Distributed hardware is also harder to patch, monitor, and physically secure than a single data center with a badge-controlled entrance and a dedicated operations team, and a node that fails at a remote mine site or an unmanned cell tower can stay broken far longer than a failed server in a cloud region with automated failover on hand.
Provider Approaches and What Comes Next
Not every company builds edge infrastructure from scratch, and the vendors that offer it differ enough in philosophy that the choice matters. Cloudflare leans on its enormous existing network of points of presence, letting developers run small pieces of logic, known as Workers, at locations close to nearly every internet user without owning any physical hardware themselves. Fastly took a similar path with its Compute platform, optimized for extremely fast cold starts on short-lived requests.
AWS approaches the problem differently through offerings like Wavelength and Outposts, extending its cloud services either into telecom networks or directly onto hardware a customer runs in their own facility. Microsoft Azure and Google Cloud both offer comparable options aimed at the same set of industrial and telecom customers.
The practical difference shows up in what a team controls day to day. A Cloudflare Worker runs in a sandboxed environment with strict limits on execution time and memory, which suits short, stateless tasks like request routing, authentication checks, or A/B test logic.
An AWS Outpost, by contrast, behaves like a slice of the AWS cloud physically located inside a customer’s data center, giving far more flexibility at the cost of far more operational responsibility. Choosing between them comes down to whether the workload is a quick, distributed function or a full application that needs to run persistently on dedicated local hardware.
Cost is another factor that surprises teams new to the space. Deploying and maintaining hundreds of small sites, each with its own hardware refresh cycle, power contract, and connectivity plan, can end up costing more in aggregate than a single well-provisioned cloud region, even though each individual node looks cheap on paper. The math only favors the edge when latency or bandwidth constraints force the issue, which is why mature engineering teams treat it as a targeted tool rather than a default architecture for every new project.
The next phase of edge computing is less about adding more locations and more about making the ones already deployed smarter. Chip makers keep shrinking the gap between what a cloud GPU can run and what a battery-powered sensor can handle, which means models once reserved for a data center are showing up on doorbell cameras and factory gateways.
Telecom carriers rolling out private 5G networks for corporate campuses are building edge compute into the network itself rather than bolting it on afterward, so a warehouse or airport can get low-latency processing without standing up separate infrastructure.
Standardization is the other piece still catching up. Right now, moving a workload between Cloudflare’s edge network, an AWS Outpost, and a telecom-operated site often means rewriting large portions of the deployment pipeline, because each platform exposes different tools and constraints. Open frameworks for orchestrating workloads across a mix of edge hardware are gaining traction, aiming to give developers something closer to the “write once, deploy anywhere” experience that centralized cloud platforms already offer. Until that maturity arrives, most teams still pick a primary edge provider and design around its specific limitations rather than building for true portability.
Final Thoughts
Edge computing isn’t a replacement for the cloud so much as an acknowledgment that not every problem fits a single architecture.
Some decisions need to happen in milliseconds, some data is too heavy to ship anywhere in full, and some sites cannot depend on a reliable connection to function. Pushing processing closer to where data originates addresses those constraints directly rather than trying to engineer around them from a distant data center.
As more physical systems, from factory floors to delivery vehicles, generate data that demands an immediate response, the edge will keep expanding, not as a trend but as a structural piece of how modern computing gets distributed.
Frequently Asked Questions
1. Is edge computing replacing the cloud entirely?
No. Most production systems use a hybrid model where the edge handles time-sensitive or bandwidth-heavy tasks while the central cloud manages training, long-term storage, and coordination across sites. The two layers complement each other rather than compete.
2. What kind of hardware runs at the edge?
It ranges from ruggedized micro data centers and telecom racks down to small accelerator chips embedded directly in cameras or sensors. The choice depends heavily on available power, space, and how much processing the local workload needs to handle.
3. Does edge computing improve security?
It can, by keeping sensitive data local rather than transmitting it over a network, but it also expands the physical attack surface since hardware sits outside a controlled data center. Both effects need to be weighed together rather than assumed as a pure win.
4. Which industries use edge computing the most today?
Manufacturing, retail, healthcare, and telecommunications lead adoption because delayed decisions in those settings carry real safety, cost, or downtime consequences. Content delivery networks were an early precursor to the pattern.
5. How is edge computing different from a CDN?
A CDN mainly caches and serves static content from locations near users, while modern edge computing runs active logic and inference at those same locations. The line between the two has blurred as CDN providers add compute capabilities.
6. Do small businesses need edge infrastructure?
Rarely on their own. Most small businesses get the benefits of edge computing indirectly through cloud and CDN providers that already operate distributed points of presence, without needing to deploy or manage any hardware themselves.